
TL;DR
Listen free for 30 days with Audible
Thousands of audiobooks and originals — cancel anytime.
Start your free trialAs an affiliate, we earn on qualifying purchases.
SenseTime chief scientist Lin Dahua told 36Kr that a major multimodal AI breakthrough moment is one to two years away. The interview was first reported by 36Kr; SenseTime did not publish the underlying transcript.
Lin Dahua, chief scientist of Chinese AI company SenseTime, said in an exclusive interview with the Chinese tech outlet 36Kr that a multimodal AI breakthrough moment — a step-change in systems that understand and generate across text, images, video and other inputs — is likely to arrive within one to two years. The prediction, reported by 36Kr, is one of the most specific timelines a senior SenseTime research leader has put on multimodal progress.
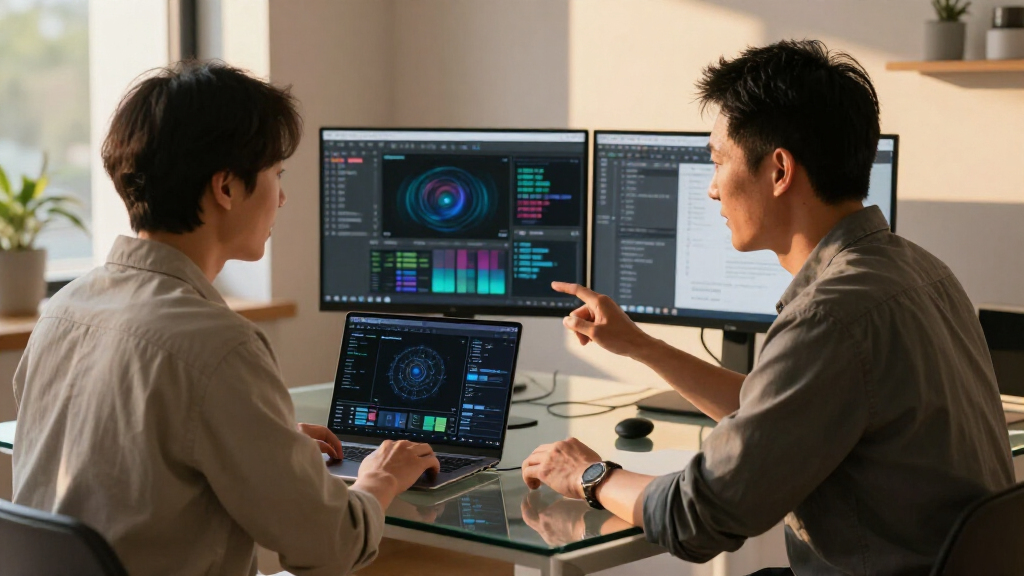
The interview centers on SenseTime’s research direction in multimodal foundation models — AI systems trained to process and connect multiple types of data, such as text, images, audio and video, rather than a single input type. According to 36Kr’s report, Lin framed the coming one-to-two-year window as the period in which multimodal capabilities could move from steady incremental improvement to a more decisive leap.
Lin Dahua is SenseTime’s chief scientist and leads the company’s research efforts. SenseTime, once best known for computer vision and facial recognition, has repositioned itself in recent years around its SenseNova foundation model platform, competing in China’s crowded large-model market alongside Baidu, Alibaba, ByteDance and a wave of startups.
Only the headline and framing of the 36Kr interview were available; the full interview text, including the specific technical claims, benchmarks or research results Lin cited to support the timeline, could not be independently reviewed.
Multimodal AI Breakthrough Moment Coming in 1–2 Years
SenseTime chief scientist Lin Dahua predicts a decisive leap in AI systems that understand and generate across text, images, audio and video — one of the most specific timelines a senior SenseTime research leader has put on multimodal progress.
Why a 1–2 Year Multimodal Timeline Matters
Investment & Expectations
Timelines from senior research leaders shape corporate investment cycles and market expectations. A short window signals where SenseTime will concentrate research resources.
Unified Assistants
If accurate, assistants that watch, listen, read and act across formats could become practical before the end of the decade — affecting autonomous driving to content creation.
US–China AI Race
Chinese AI firms are under pressure to differentiate from OpenAI and Google. SenseTime argues its long history in vision gives it an edge in models that combine seeing and reasoning.
From Computer Vision to Foundation Models
Vision Era
SenseTime built its business on computer vision, including facial recognition, becoming one of China’s largest AI companies.
Repositioning
The company repositioned around its SenseNova foundation model platform as the large-model market grew crowded.
Multimodal Core
Multimodal research is emphasized as a core differentiator, merging text, image, audio and video into single systems.
Video Frontier
Video understanding has become one of the most active competitive fronts across the global industry.
Where Multimodal Progress Stands
Editorial assessment of recent progress and competitive intensity by modality. Past-two-year gains in video and image understanding surprised many observers — the strongest counterargument to skepticism about a short timeline.
What the Interview Does — and Doesn’t — Tell Us
| Question | Status | Detail |
|---|---|---|
| Full interview transcript | ✗ Unavailable | Only headline and framing were accessible; underlying text not published by SenseTime. |
| Definition of “breakthrough moment” | ~ Unclear | Industry-wide progress vs. SenseTime’s own products — scope not specified. |
| Supporting benchmarks | ✗ None public | No technical milestones, scaling observations or internal benchmarks disclosed. |
| Prediction status | ~ Forecast | A claim by a company executive, not a verified technical result. |
| Testable milestones ahead | ✓ Yes | Next SenseNova releases, published multimodal benchmarks, and 12–24 months of industry releases. |
Credible Signal — Expectation, Not Fact
Published benchmarks showing a qualitative jump in unified multimodal reasoning, or SenseTime product releases that demonstrably outperform current systems within the stated 1–2 year window.
A plateau in video-understanding results over the next year. Senior researchers elsewhere have made similar short-horizon predictions before, with mixed results.
Why a 1-2 Year Multimodal Timeline Matters
Timelines from senior research leaders shape corporate investment cycles and market expectations. If Lin’s one-to-two-year estimate is accurate, products built on unified multimodal models — assistants that watch, listen, read and act across formats — could become practical before the end of the decade, affecting industries from autonomous driving to content creation.
The prediction also matters competitively. Chinese AI firms are under pressure to differentiate from US rivals such as OpenAI and Google, whose own multimodal models have set the pace. A senior figure at one of China’s largest AI companies publicly committing to a short timeline signals where SenseTime intends to concentrate its research resources.
As an affiliate, we earn on qualifying purchases.
SenseTime’s Shift From Vision to Foundation Models
SenseTime built its business on computer vision, including facial recognition, and has since expanded into large foundation models with its SenseNova platform. The company has emphasized multimodal research as a core differentiator, arguing that its long history in vision gives it an advantage in models that combine seeing and reasoning.
The global industry trend supports that focus: leading model developers have progressively merged text, image, audio and video capabilities into single systems, and video understanding has become one of the most active competitive fronts.
“The multimodal AI breakthrough moment is coming in one to two years.”
— Lin Dahua, SenseTime chief scientist (as reported by 36Kr)
AI image and video annotation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What the Interview Doesn’t Tell Us
The full text of the 36Kr interview could not be accessed, so the reasoning behind the one-to-two-year estimate — whether it rests on specific technical milestones, scaling observations or internal benchmarks — is unknown. It is not clear whether Lin defined what counts as a “breakthrough moment,” whether he meant industry-wide progress or SenseTime’s own products, or which modalities he considers closest to a leap.
Predictions of this kind are claims, not confirmed facts. AI capability timelines have historically been both over- and under-estimated, and no external benchmark currently validates this one.
As an affiliate, we earn on qualifying purchases.
Milestones That Could Test the Prediction
Watch for SenseTime’s next SenseNova model releases and any published multimodal benchmarks, which would show whether its systems are approaching the capability jump Lin described. Industry-wide, successive releases of video-understanding and unified multimodal models over the next 12–24 months will provide the clearest test of the timeline. A fuller transcript or follow-up statements from SenseTime would also clarify the scope of the claim.
audio and video processing AI tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Where I land
My read: a one-to-two-year timeline for a multimodal leap from SenseTime’s chief scientist is a credible signal of where the field is heading, but it should be treated as an expectation, not a fact. Senior researchers at competing labs have made similar short-horizon predictions before, with mixed results, and executives have natural incentives to project momentum.
The strongest counterargument to skepticism is that multimodal progress over the past two years has been unusually fast — video and image understanding have improved at a rate that surprised many observers — so a short timeline is not unreasonable.
What would change my assessment: published benchmarks showing a qualitative jump in unified multimodal reasoning, or SenseTime product releases that demonstrably outperform current systems within the stated window. Conversely, a plateau in video-understanding results over the next year would weaken the claim.
Source: SenseTime
Key Questions
Who is Lin Dahua?
Lin Dahua is the chief scientist of SenseTime, one of China’s largest AI companies, and leads its research organization.
What did he predict?
In an interview with 36Kr, Lin said a multimodal AI breakthrough moment is likely to arrive within one to two years.
Is this prediction confirmed or just a forecast?
It is a forecast by a company executive, not a verified technical result. No benchmark or published data currently confirms the timeline.
Why does multimodal AI matter?
Multimodal models process text, images, audio and video together, enabling applications such as video understanding, richer assistants, and systems that perceive and act in physical environments.
Where was the interview published?
The interview was conducted by the Chinese technology outlet 36Kr; the full text was not available for independent review.
Source: SenseTime
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.